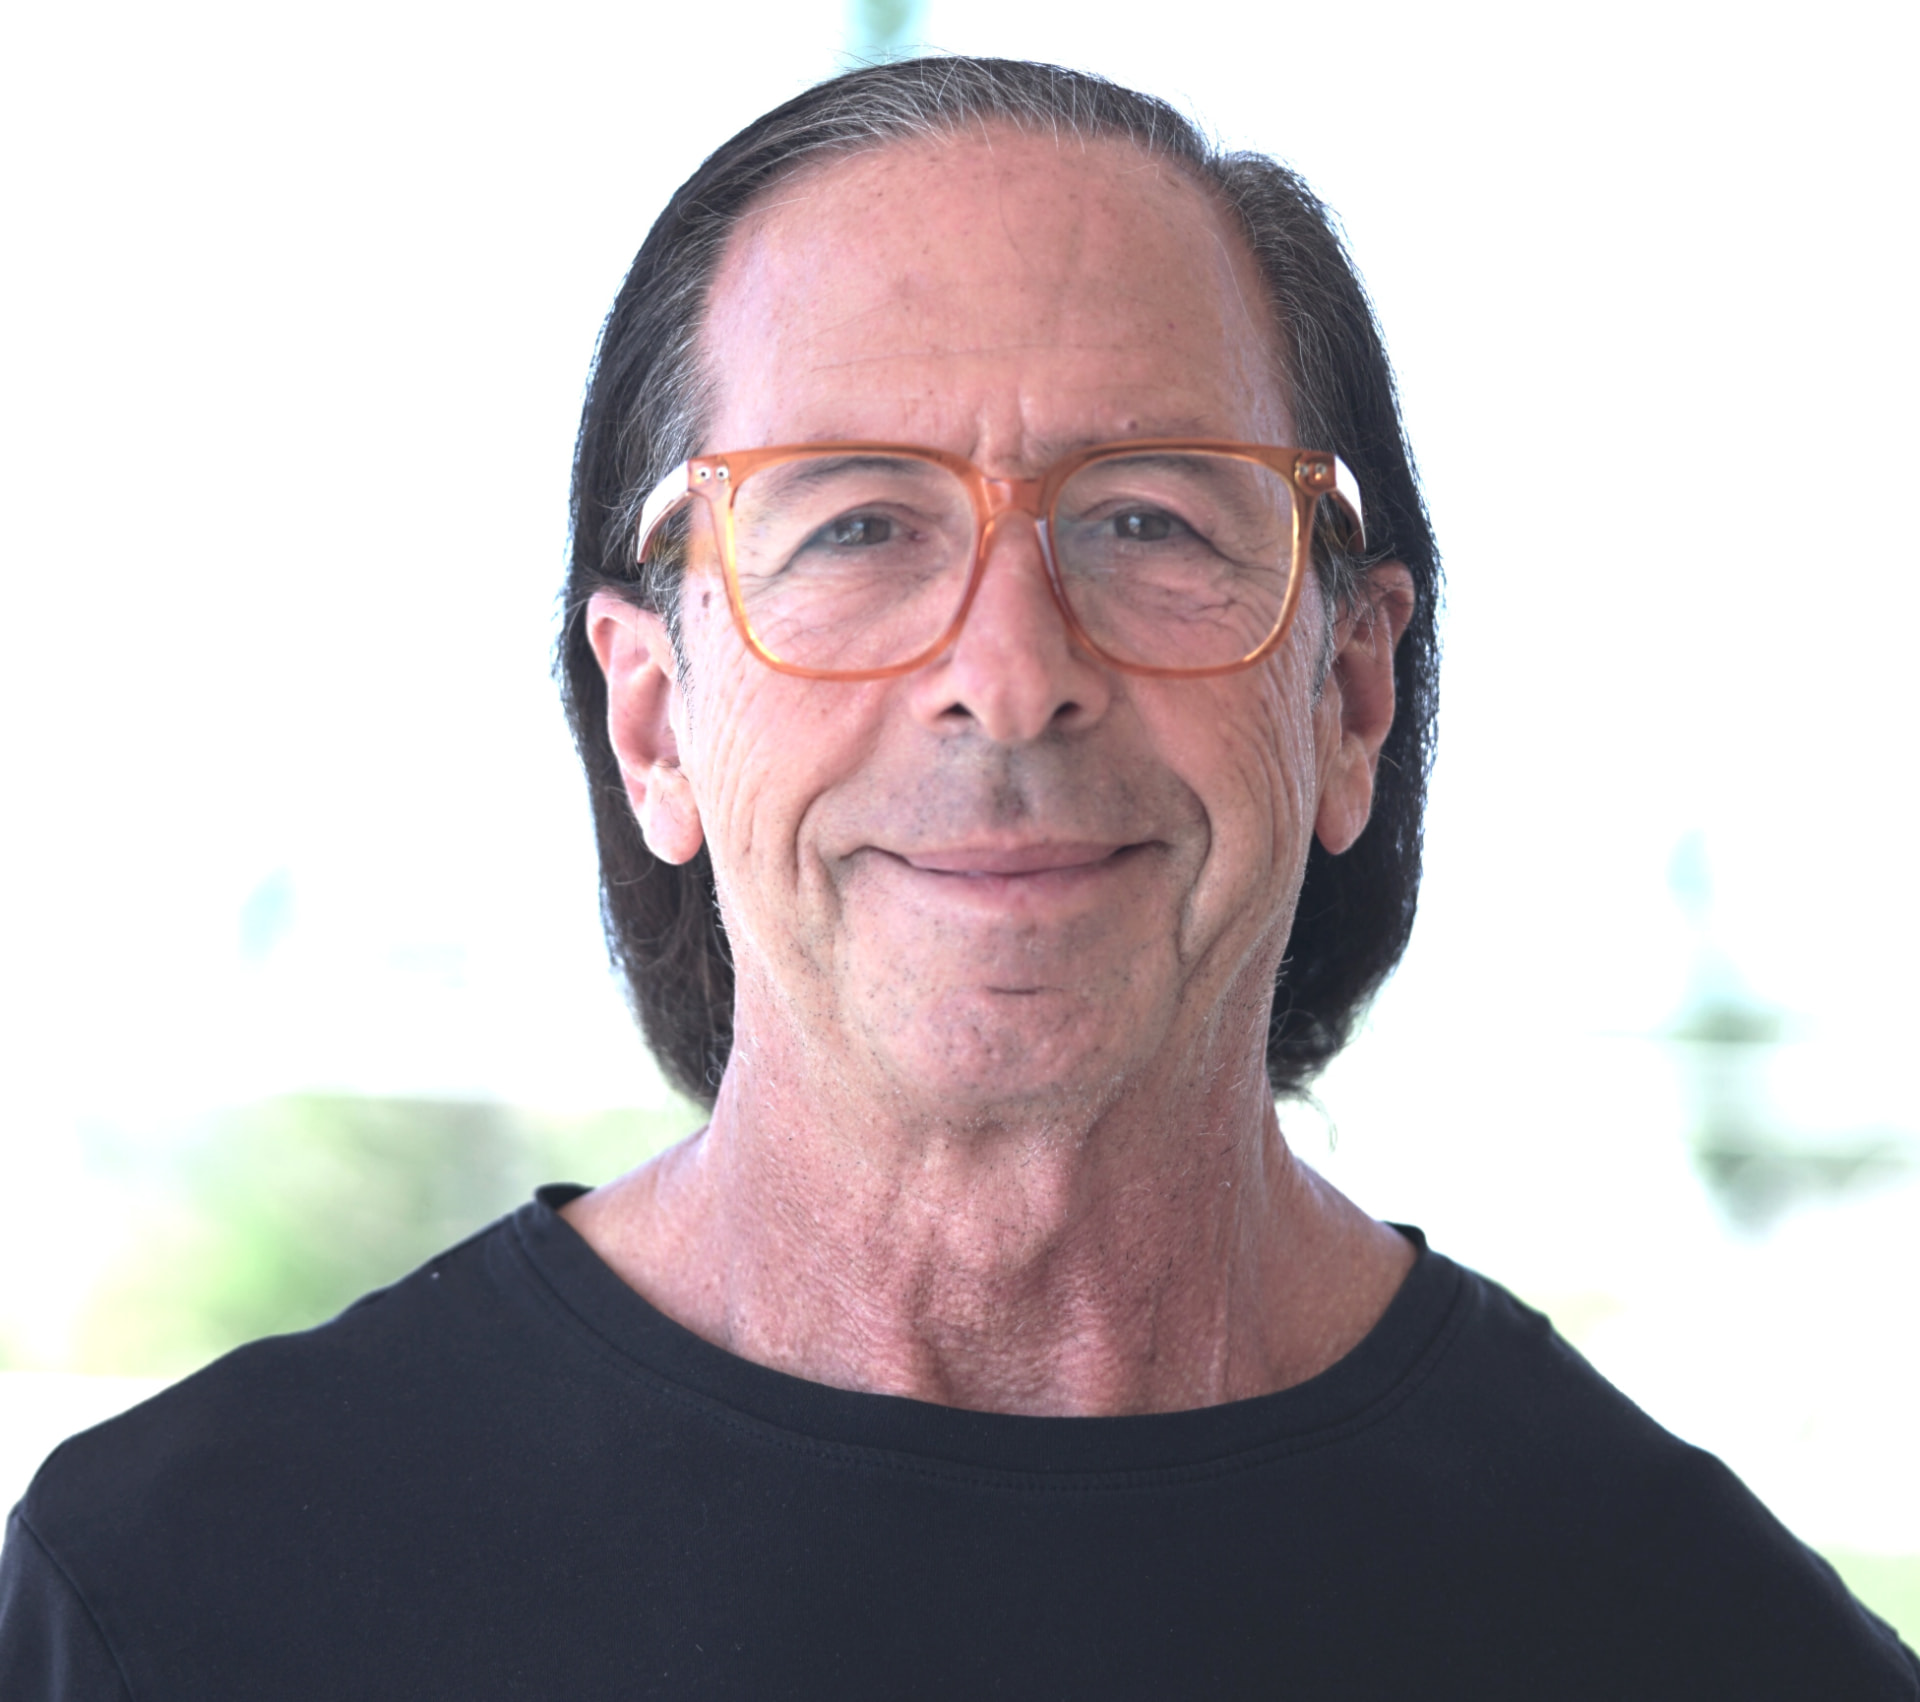
Host
Paul Bryan
Producer, STRAT Conference, and Founder, Reset Institute
13+ years leading global product design strategy conferences (STRAT) and enterprise workshops, with a focus on human-centered AI product design.
Rigorous quantitative and qualitative research uncovering why users and employees adopt or abandon your AI systems. No psychological tricks, just demonstrably trustworthy product design.
“Trust is going to be the biggest issue for us.”
Satya Nadella, CEO of Microsoft
Yahoo Finance Interview
of enterprise AI pilots fail to reach production due to trust, agency & risk control gaps.
*Source: MIT & Gartner Enterprise AI Benchmarks
higher workflow performance when AI tools feature human controls.
*Source: Gartner AI Workplace Benchmarks
of workers trust AI for business-critical decisions, versus 61% of executives.
*Source: WalkMe, State of Digital Adoption 2026
The Framework
Every engagement is evaluated against three pillars, the foundation of demonstrably trustworthy AI products.
User Sovereignty & Control
Risk Mitigation & Guardrails
Utility & System Predictability
Unfiltered conversations at the intersection of AI product strategy, user agency, and global research scale.
Host
Producer, STRAT Conference, and Founder, Reset Institute
13+ years leading global product design strategy conferences (STRAT) and enterprise workshops, with a focus on human-centered AI product design.
Why Listen
Every episode dissects the hard data behind user trust, moving beyond AI hype to examine what makes products genuinely safe, useful, and empowering.
Services
Each service detects a specific behavior, so you learn which trust failure you have and what to change. The full menu, with what each one measures, lives on the services page.
What the numbers show about trust, at scale.
2 services
The behaviors and reasons the numbers cannot see.
7 services
What each service measures, and how to combine them into an engagement.
Interactive Diagnostic
What do you know about your AI product, and what are you assuming? Score each item by the evidence you have.
Scoring key
00 = Don't know
11 = We assume
22 = We've seen it informally
33 = We've measured it
“Don't know” answers are honest, and every one of them is a research engagement.
We know how often the AI is wrong, by task type
Research basis: Ground truth for appropriate reliance
We know whether users check output more or less than its error rate warrants
Research basis: Verification effort, both tails
We've tested whether users catch planted errors before launch
Research basis: Automation bias research
Users can edit, steer, or partially accept output
Research basis: Dietvorst 2018
Users can preview and approve before the AI acts
Research basis: Levels of automation
We know which tasks users refuse to hand to the AI, and why
Research basis: Task-dependent aversion
We know what happens to usage after a user's first visible error
Research basis: First-error cliff
We've tested that our uncertainty cues reduce overreliance rather than increase it
Research basis: Mitigation backfire findings
Mistakes can be undone, and users know it
Research basis: Recoverability
We know what data users withhold, and why
Research basis: Privacy calculus
We know whether people use outside AI tools or hide their use
Research basis: Shadow AI, concealment
It's clear who is accountable when the AI is wrong
Research basis: Accountability diffusion
FREE SAMPLE AI TRUST REVIEW
Schedule an initial 45-minute AI Trust Review. We'll evaluate your AI product against our 3 Pillar Trust Framework.